Zero-shot wildfire smoke segmentation, scored against ground truth
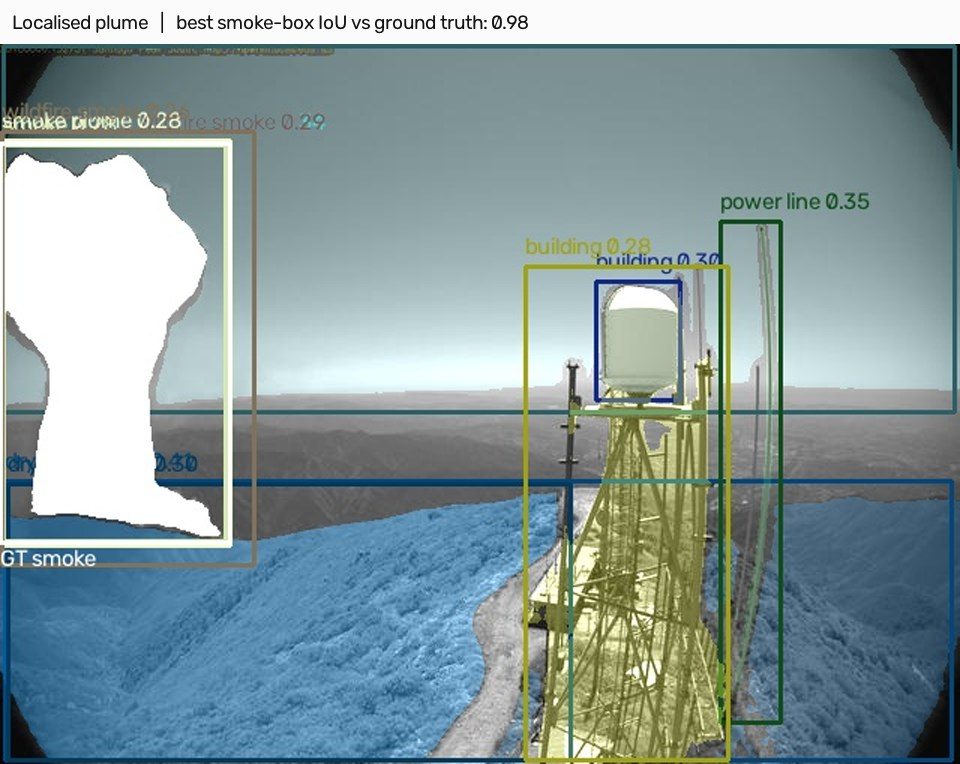
I scored a Grounding DINO + SAM zero-shot pipeline against 744 annotated plumes, raised localisation from 36% to 51% through prompt design, and put the MobileSAM encoder on TensorRT at 4.3 ms.
- Role
- Pipeline, ground-truth scoring, prompt experiments and TensorRT export
- Setting
- Offline evaluation on still images from many cameras · encoder benchmarked on a workstation GPU
- Stack
- Grounding DINO
- Segment Anything
- MobileSAM
- TensorRT
- ONNX
- PyTorch
Key results
- plumes localised
50.8%
plumes localised
IoU ≥ 0.5, 744 images
- AP50
0.304
AP50
with cross-phrase NMS
- MobileSAM encoder on TensorRT
4.31 ms
MobileSAM encoder on TensorRT
1024², mean over 698 runs, p99 4.38 ms
01
Problem & constraints
Early smoke detection matters most when plumes are small and faint, and labelled data for every camera and season does not exist. Foundation models promise text-prompted segmentation with no training; their claims need checking against ground truth.
02
My contribution
Pipeline, ground-truth scoring, prompt experiments and TensorRT export
- Built the text → boxes → masks pipeline (Grounding DINO Swin-T → SAM ViT-H).
- Scored detections against the 744 Pascal-VOC smoke boxes: recall, hit@IoU, precision, AP50.
- Ran the prompt experiments and the cross-phrase NMS fix.
- Exported the MobileSAM encoder to ONNX/TensorRT and timed it.
- Removed an unsupported claim from the original demo video (see failures).
03
System architecture
01 · Input
data
Lookout-camera frame
data
Text prompt
smoke + synonyms
02 · Ground
model
Grounding DINO Swin-T
box 0.25 / text 0.20
03 · Segment
model
SAM ViT-H
box prompts → masks
04 · Score
process
vs GT boxes
recall · precision · AP50
05 · Edge path
system
MobileSAM → TensorRT
4.31 ms / frame
04
Evaluation
- Dataset
- AI For Mankind HPWREN smoke boxes: 744 images, one annotated plume each
- Hit
- Smoke box with IoU ≥ 0.5 against the annotated plume
- Timing
- MobileSAM image encoder only, FP32 graph, TensorRT, RTX 5080
| Prompt v1 | Prompt v2 (+ synonyms) | v2 + cross-phrase NMS | |
|---|---|---|---|
| Images with any smoke detection | 59.3% | 77.7% | 77.7% |
| Plume localised (IoU ≥ 0.5) | 35.5% | 50.8% | 50.7% |
| Precision of smoke boxes | 57.4% | 24.2% | 47.3% |
| AP50 | 0.255 | 0.267 | 0.304 |
05
Results
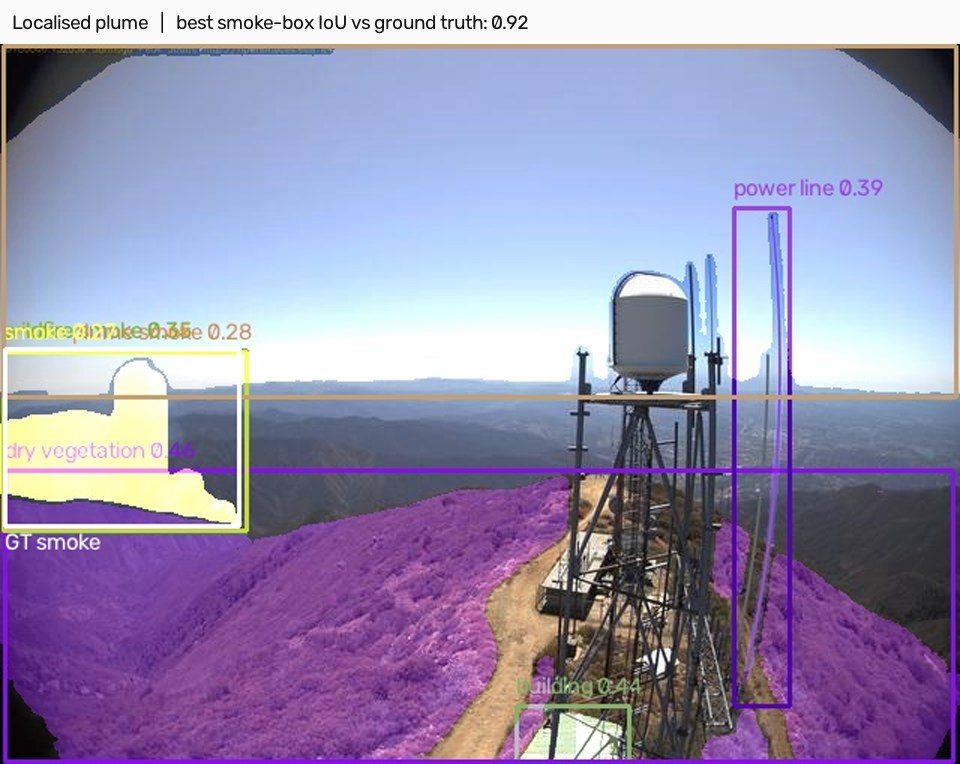
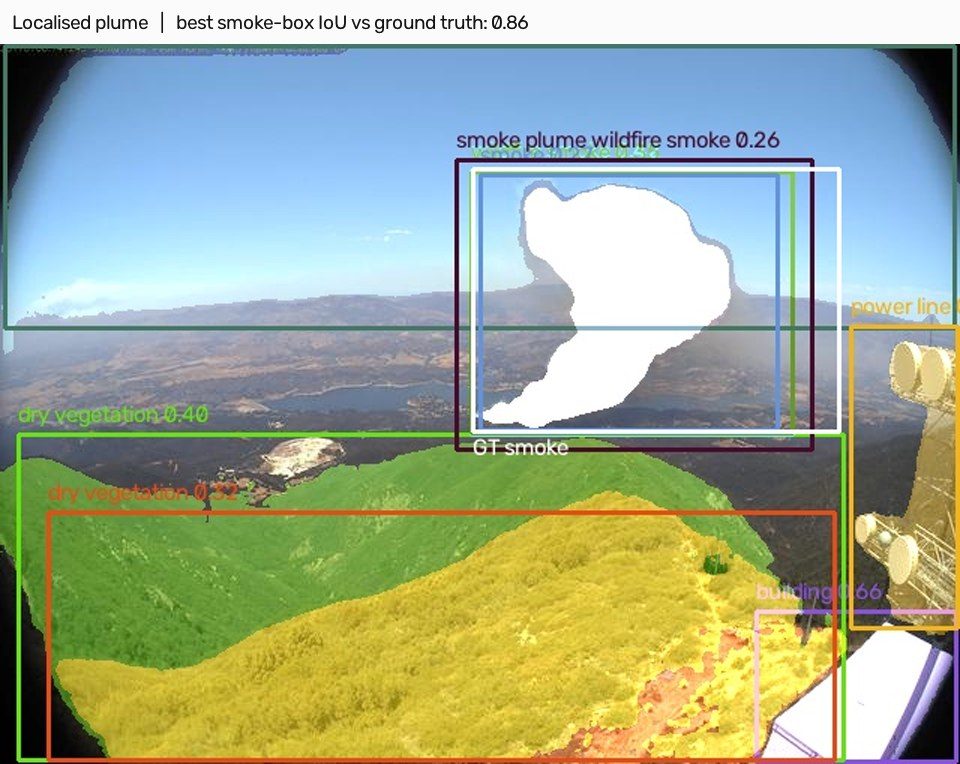
06
Failures, limits & next steps
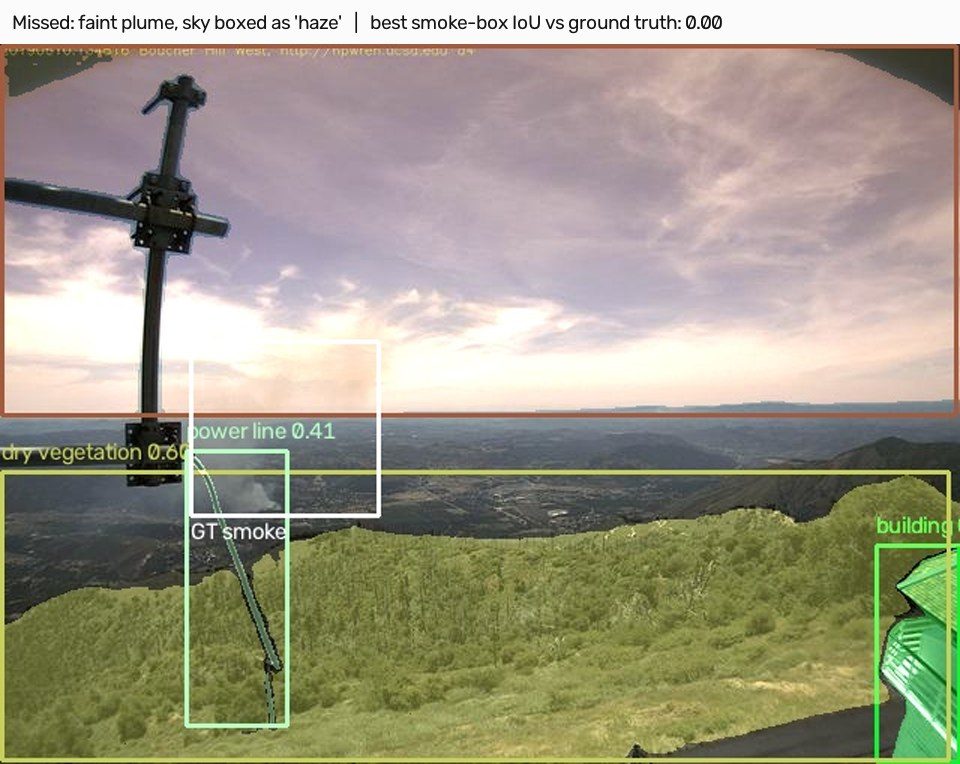
Faint plumes
A faint plume is missed and the sky is boxed as 'haze' instead.
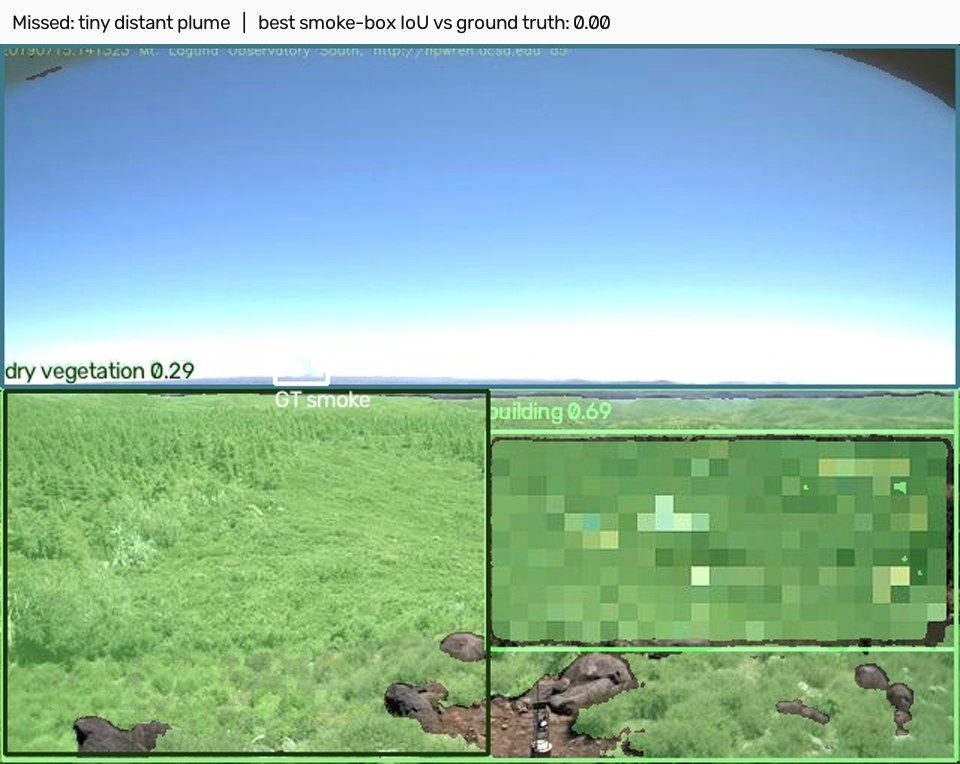
Tiny, distant plumes
Small plumes far from the camera are missed.
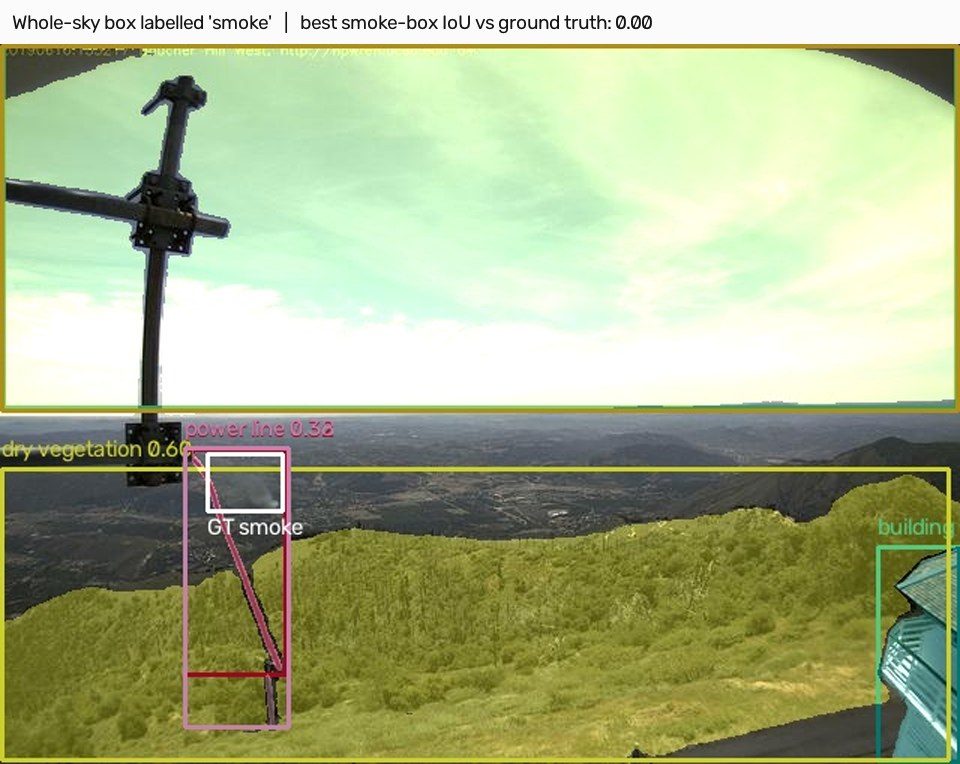
Whole-sky boxes
A box covering the entire sky swallows the plume.
A demo claim that did not hold
The original video drew a smoke 'trajectory' and overlaid '232 FPS'. The 744 images come from many cameras and days, so consecutive frames are unrelated, and 232 FPS was the MobileSAM encoder alone. The video is no longer presented as a result.
Next steps · what would prove it
- A real HPWREN time-lapse sequence for temporal tracking.
- End-to-end TensorRT pipeline including the grounding model.
- Per-distance recall to quantify small-plume performance.
07
Code & references
- Liu et al., Grounding DINO, 2023.
- Kirillov et al., Segment Anything, 2023.
- Zhang et al., MobileSAM, 2023.
DataSmoke annotations: AI For Mankind on public-domain HPWREN images, CC BY-NC-SA 4.0.
Related projects
Next: BEV perceptionComputer Vision · Edge Deployment
Real-time surgical tool detection, from dataset to device link
I validated a surgical-tool detector at 0.963 mAP50 over 5 folds, deployed it as a 0.87 ms TensorRT engine behind a Qt panel and a C++ serial relay, and measured an honest cross-dataset drop to 0.17.
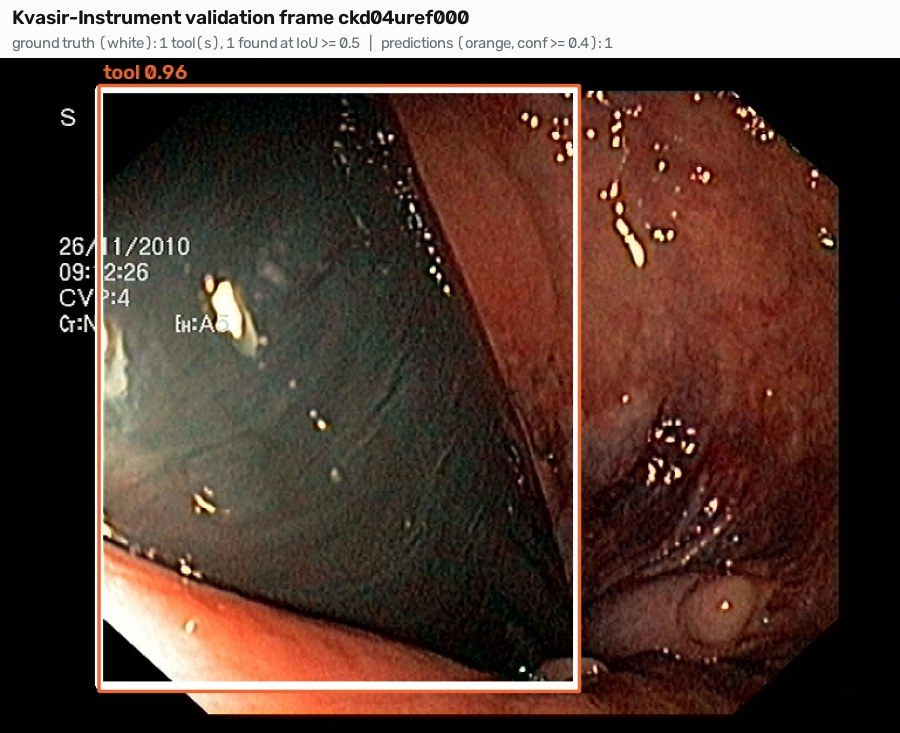
0.963mAP50 across 5 folds
Computer Vision · Deep Learning
Industrial defect segmentation with a C++ TensorRT app
I trained YOLO11-seg on MVTec AD to 0.82 mask mAP50, wrote the C++ TensorRT app that serves it, and found that rebalancing VisA's data lifted mask mAP50 from 0.25 to 0.41 where a bigger model did nothing.
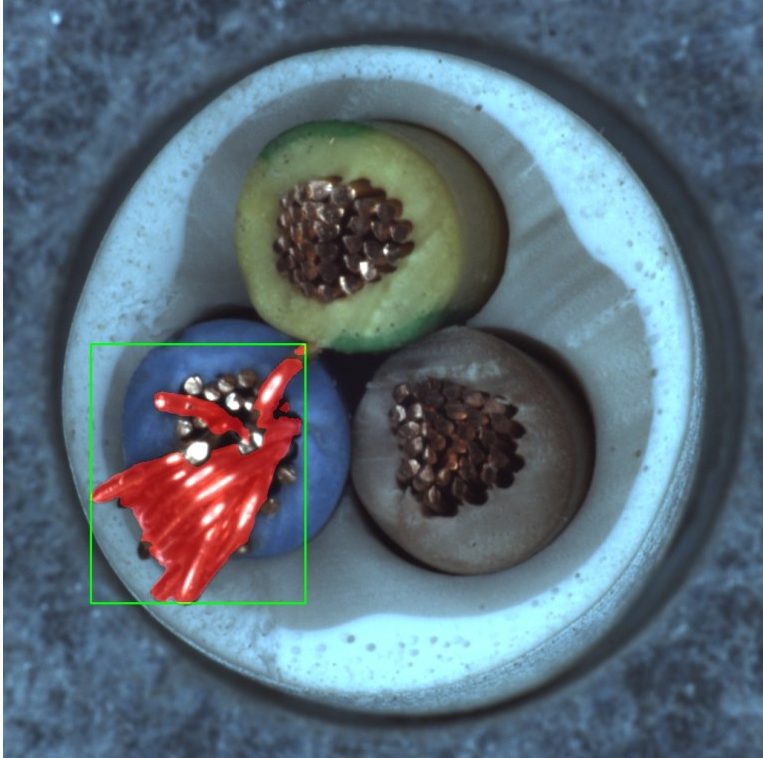 Ground truthC++ output
11 / 15held-out defects located by the C++ app
Deep Learning · Autonomous Systems
Pedestrian crossing intent with a vision-language model
I fine-tuned Qwen2-VL-2B with QLoRA to 100% valid JSON, then showed on held-out clips that its intent decision stayed at the majority baseline, traced why, and measured what a VLM does to a real-time tracker.
100%valid JSON after fine-tuning
Contact
Want to go deeper on this project? I'm happy to walk through it.
Open to full-time engineering roles. If the problem is hard and the data is messy, I'm interested.